Research
Part 1May 2026
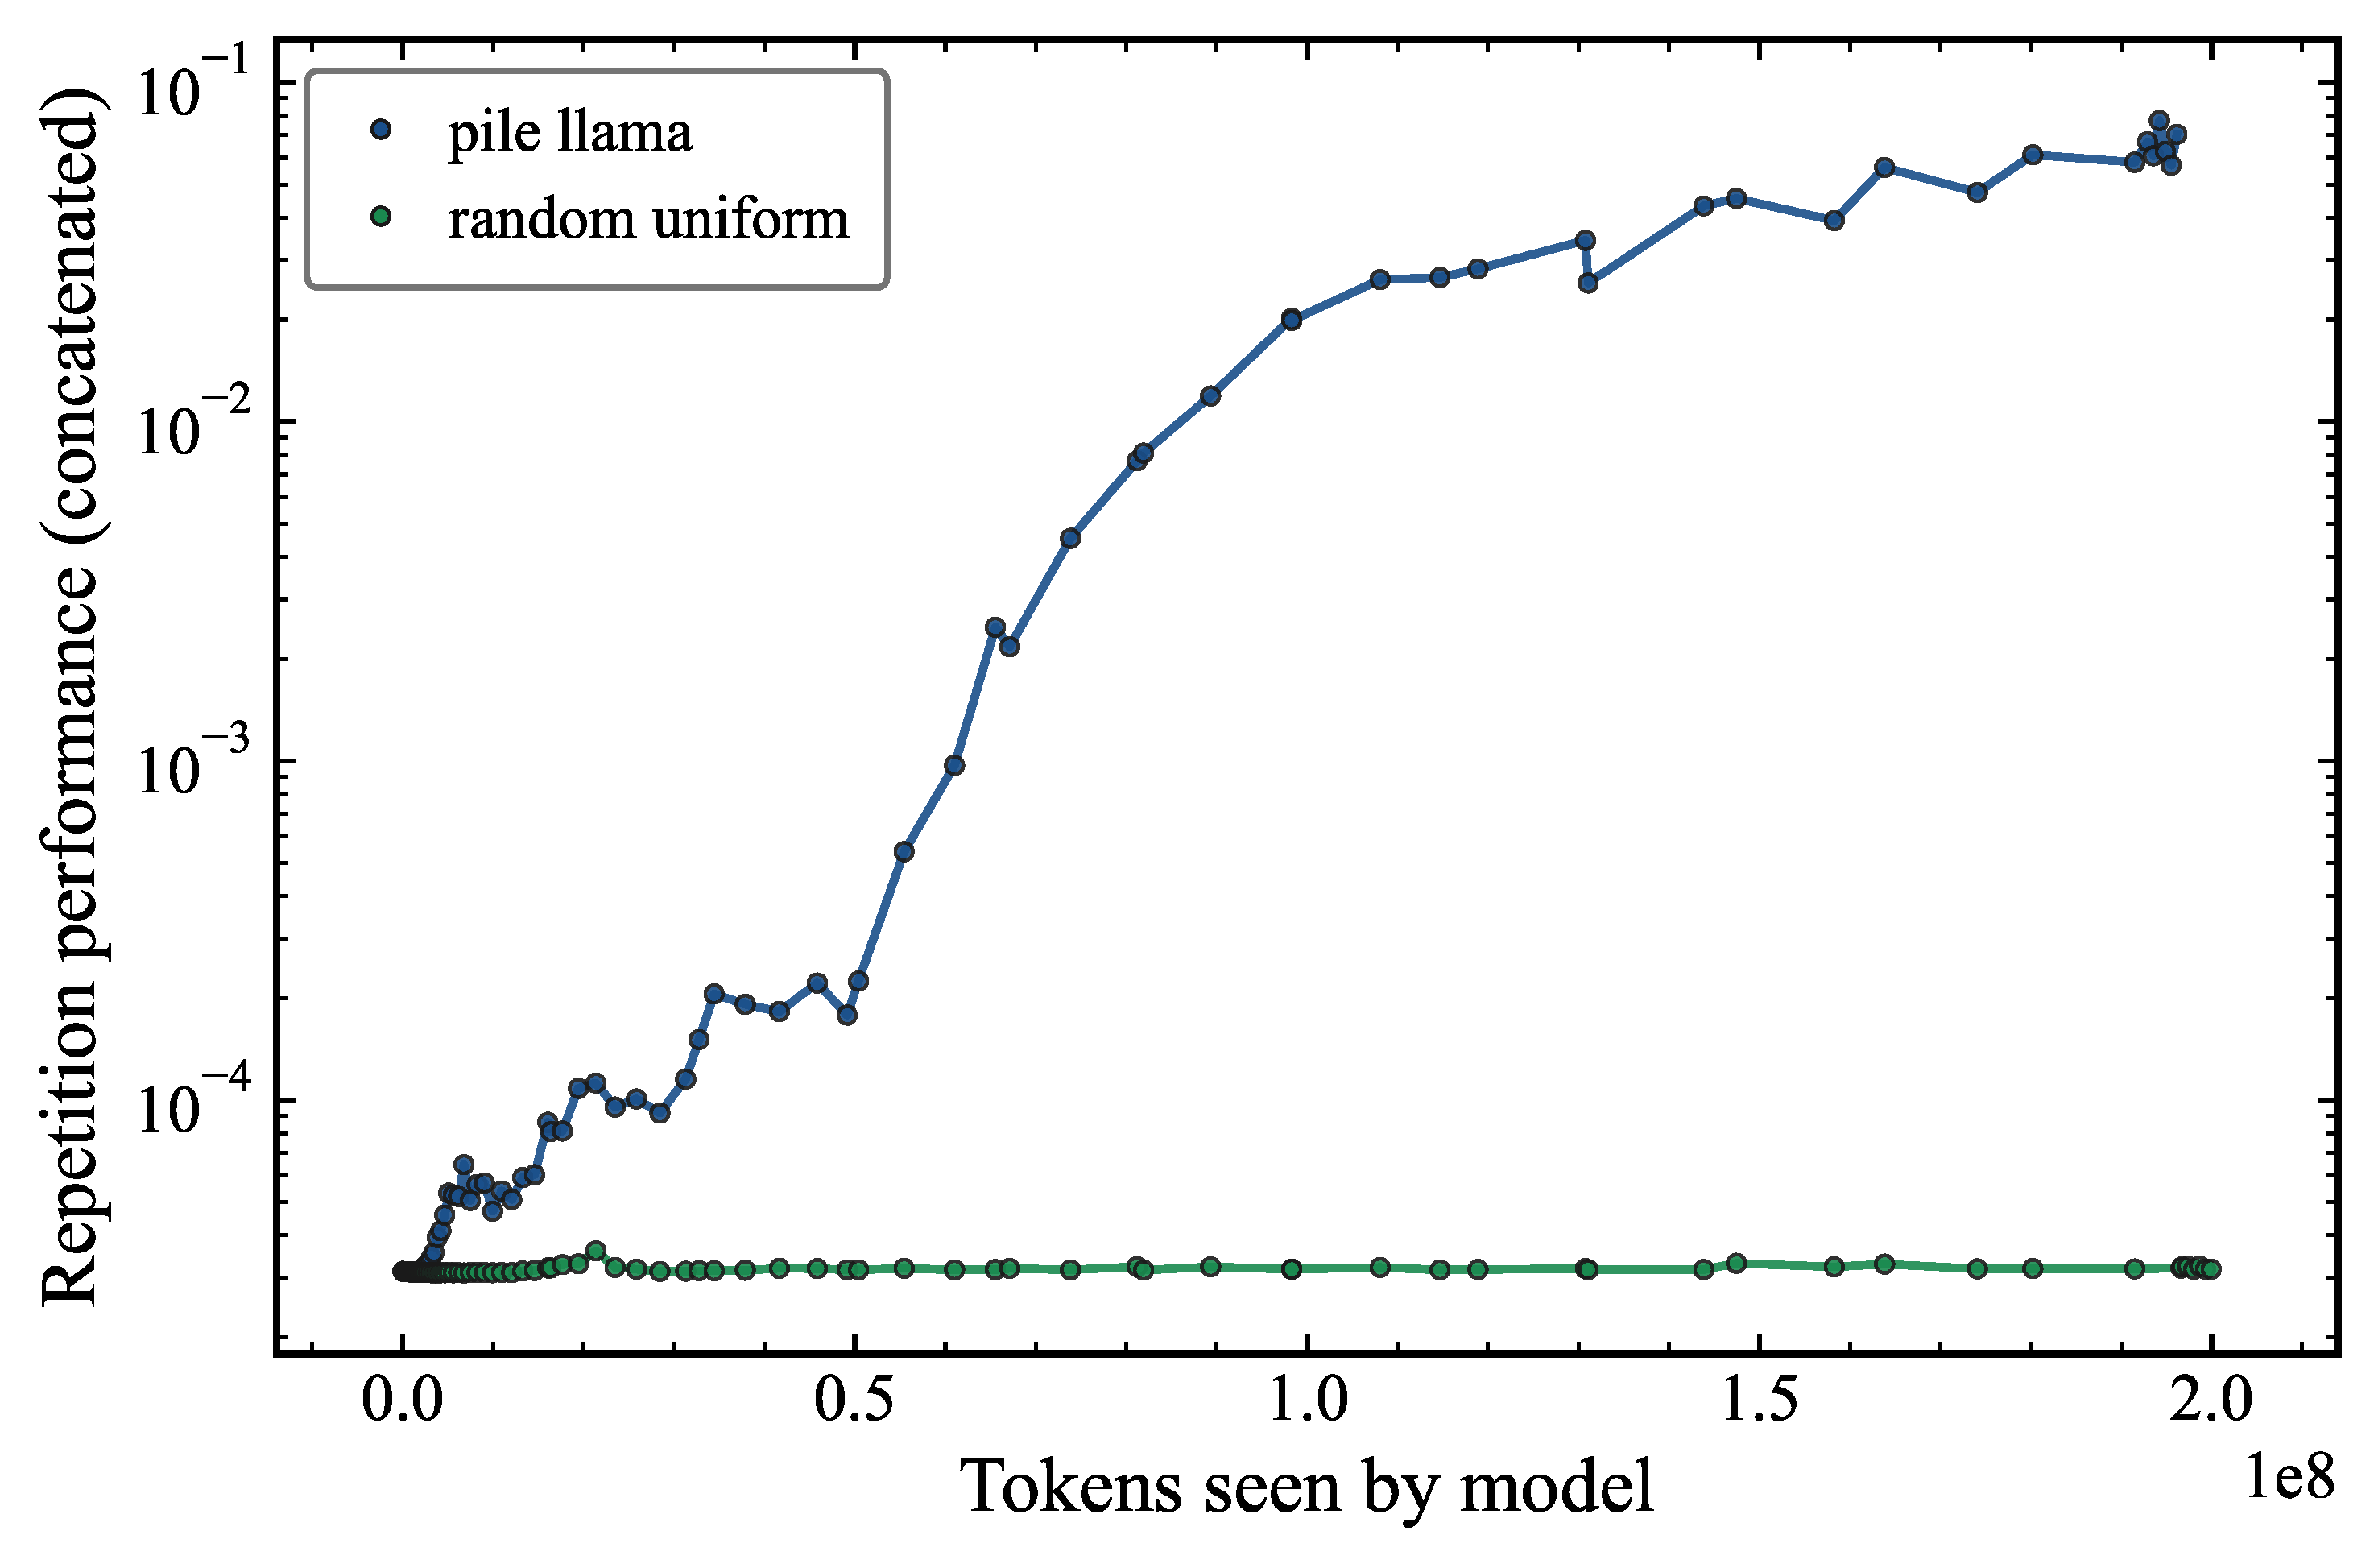
An introduction to our investigation into repetition capability in toy transformer models
Why we want to study repetition in toy transformer models and what we aim to investigate
toy-modelsinduction
Part 2May 2026
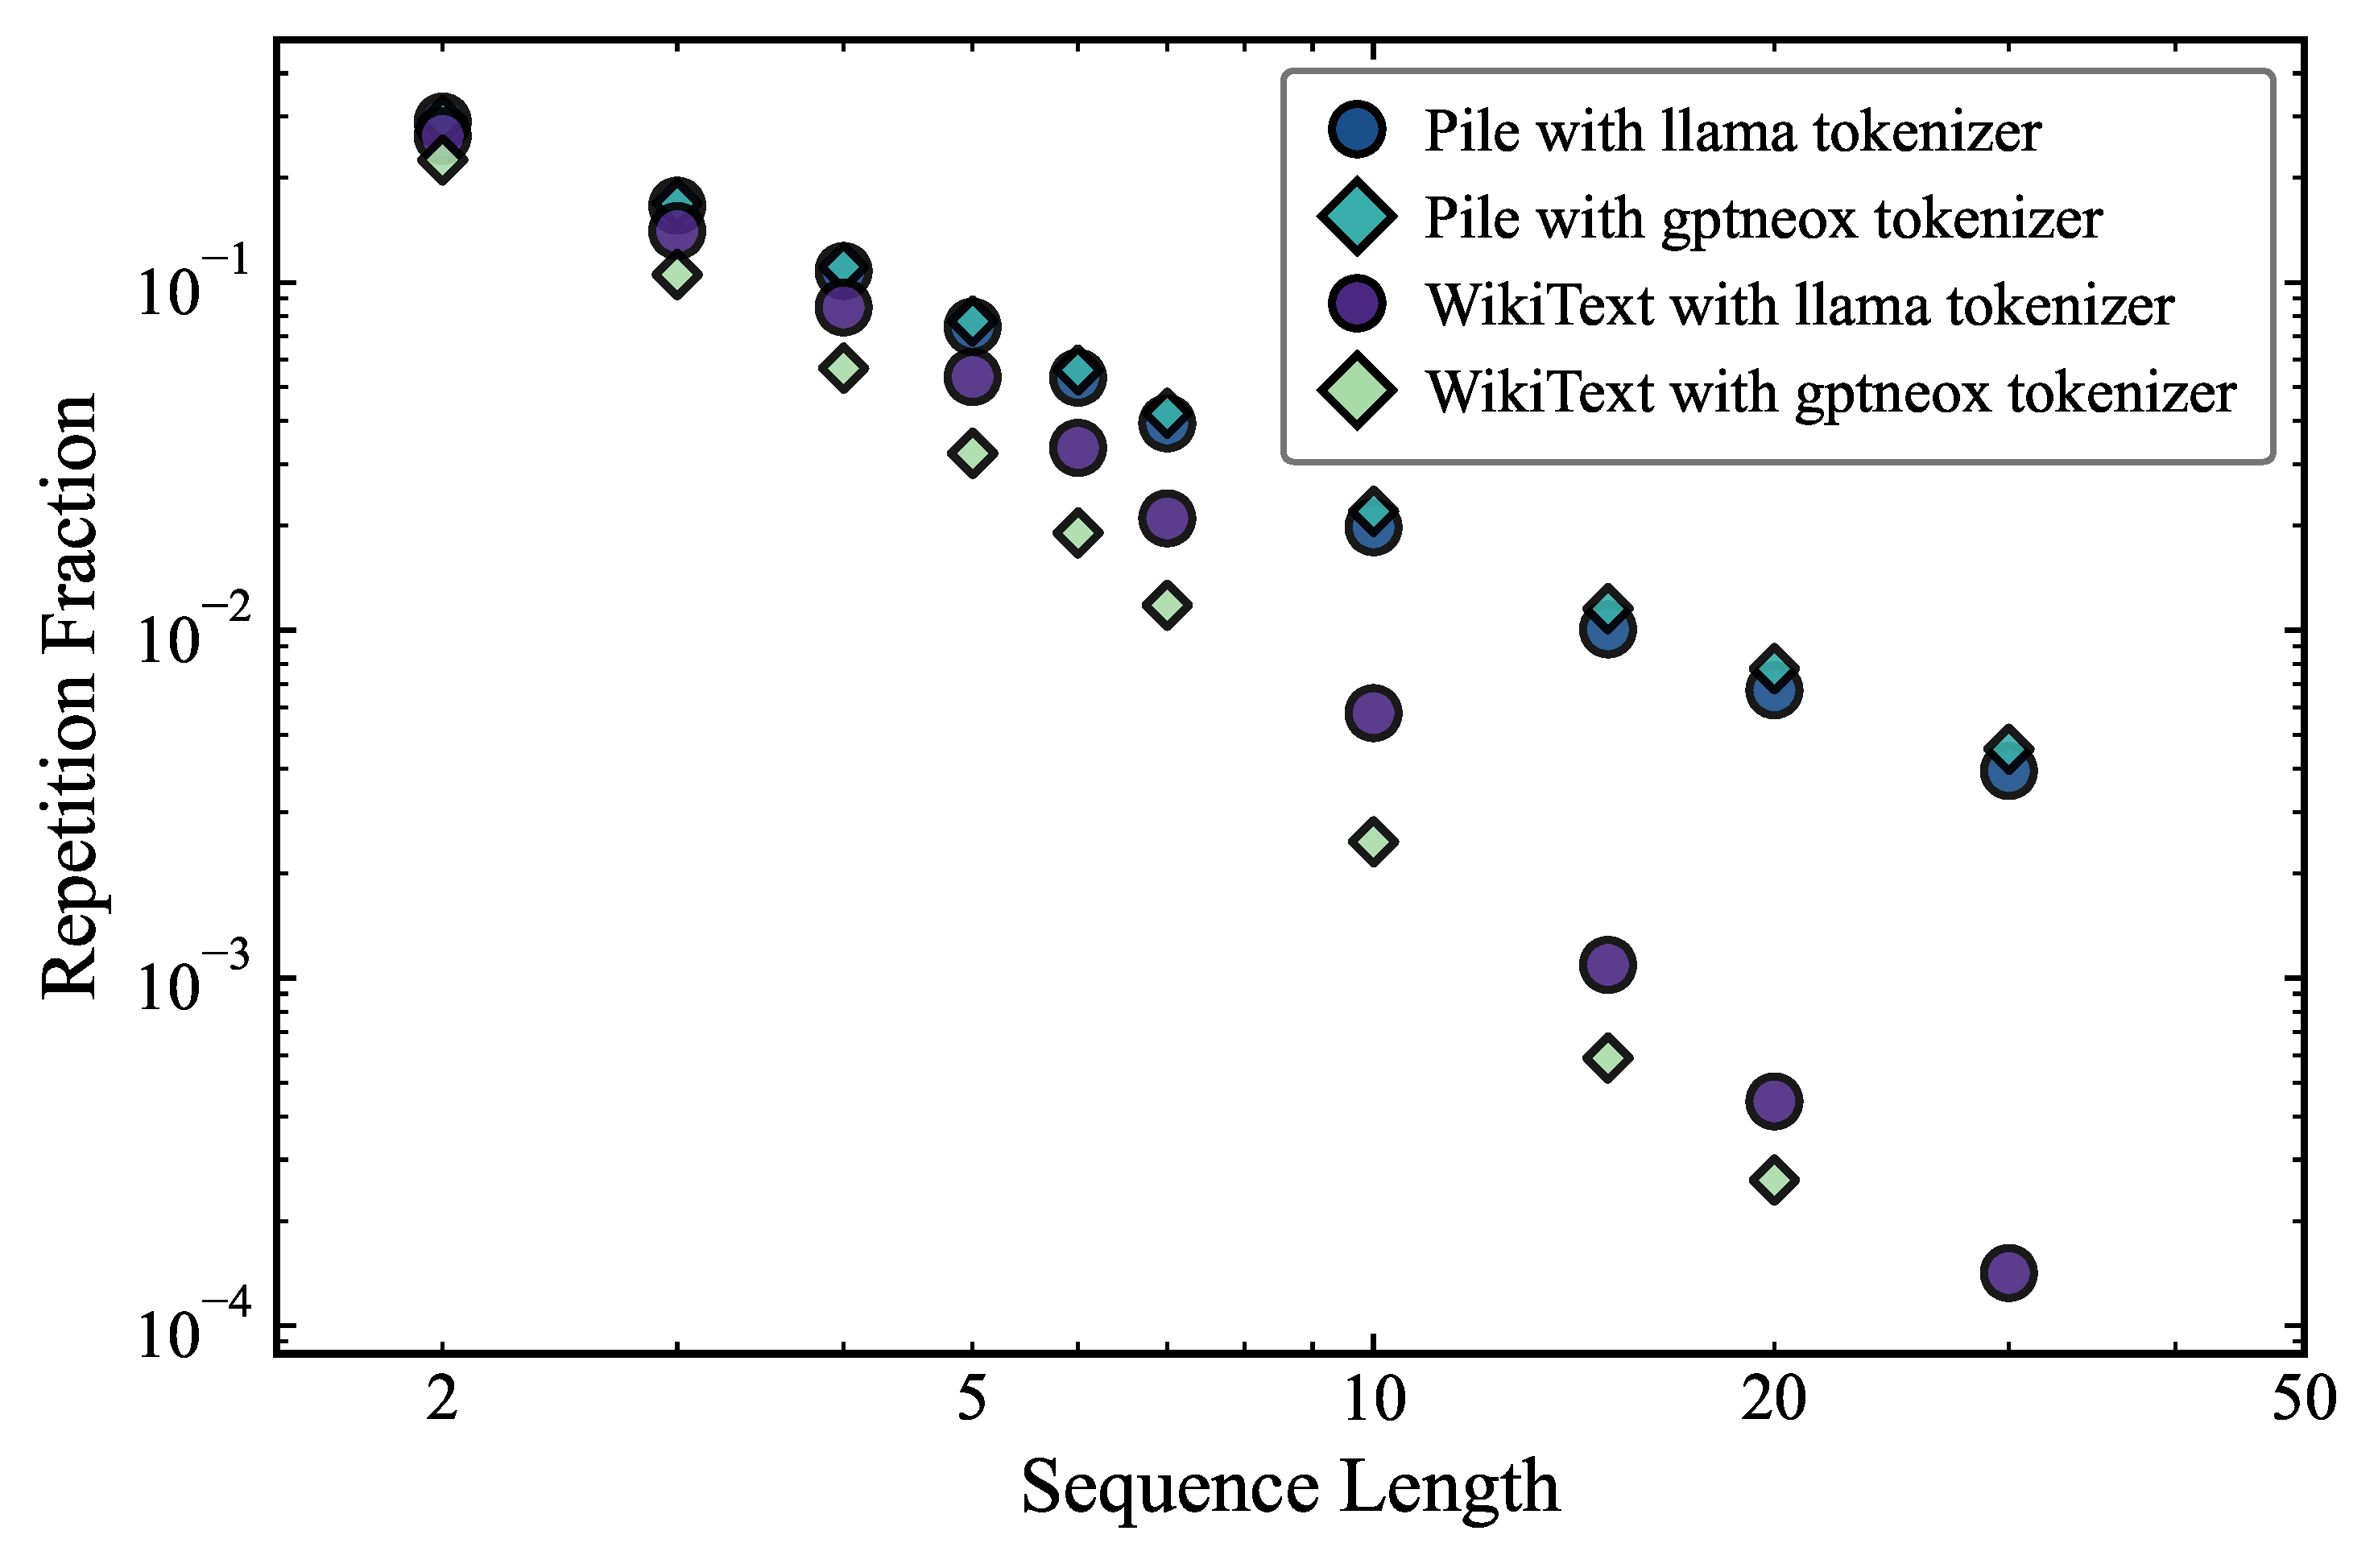
Repetition is surprisingly ubiquitous in tokenized natural language
55% of tokens in the tokenized Pile dataset are part of repeated sequences, defined as either A or B in ...AB...AB, and we characterise the structure of those repetitions in detail.
training-datainduction
Part 3May 2026
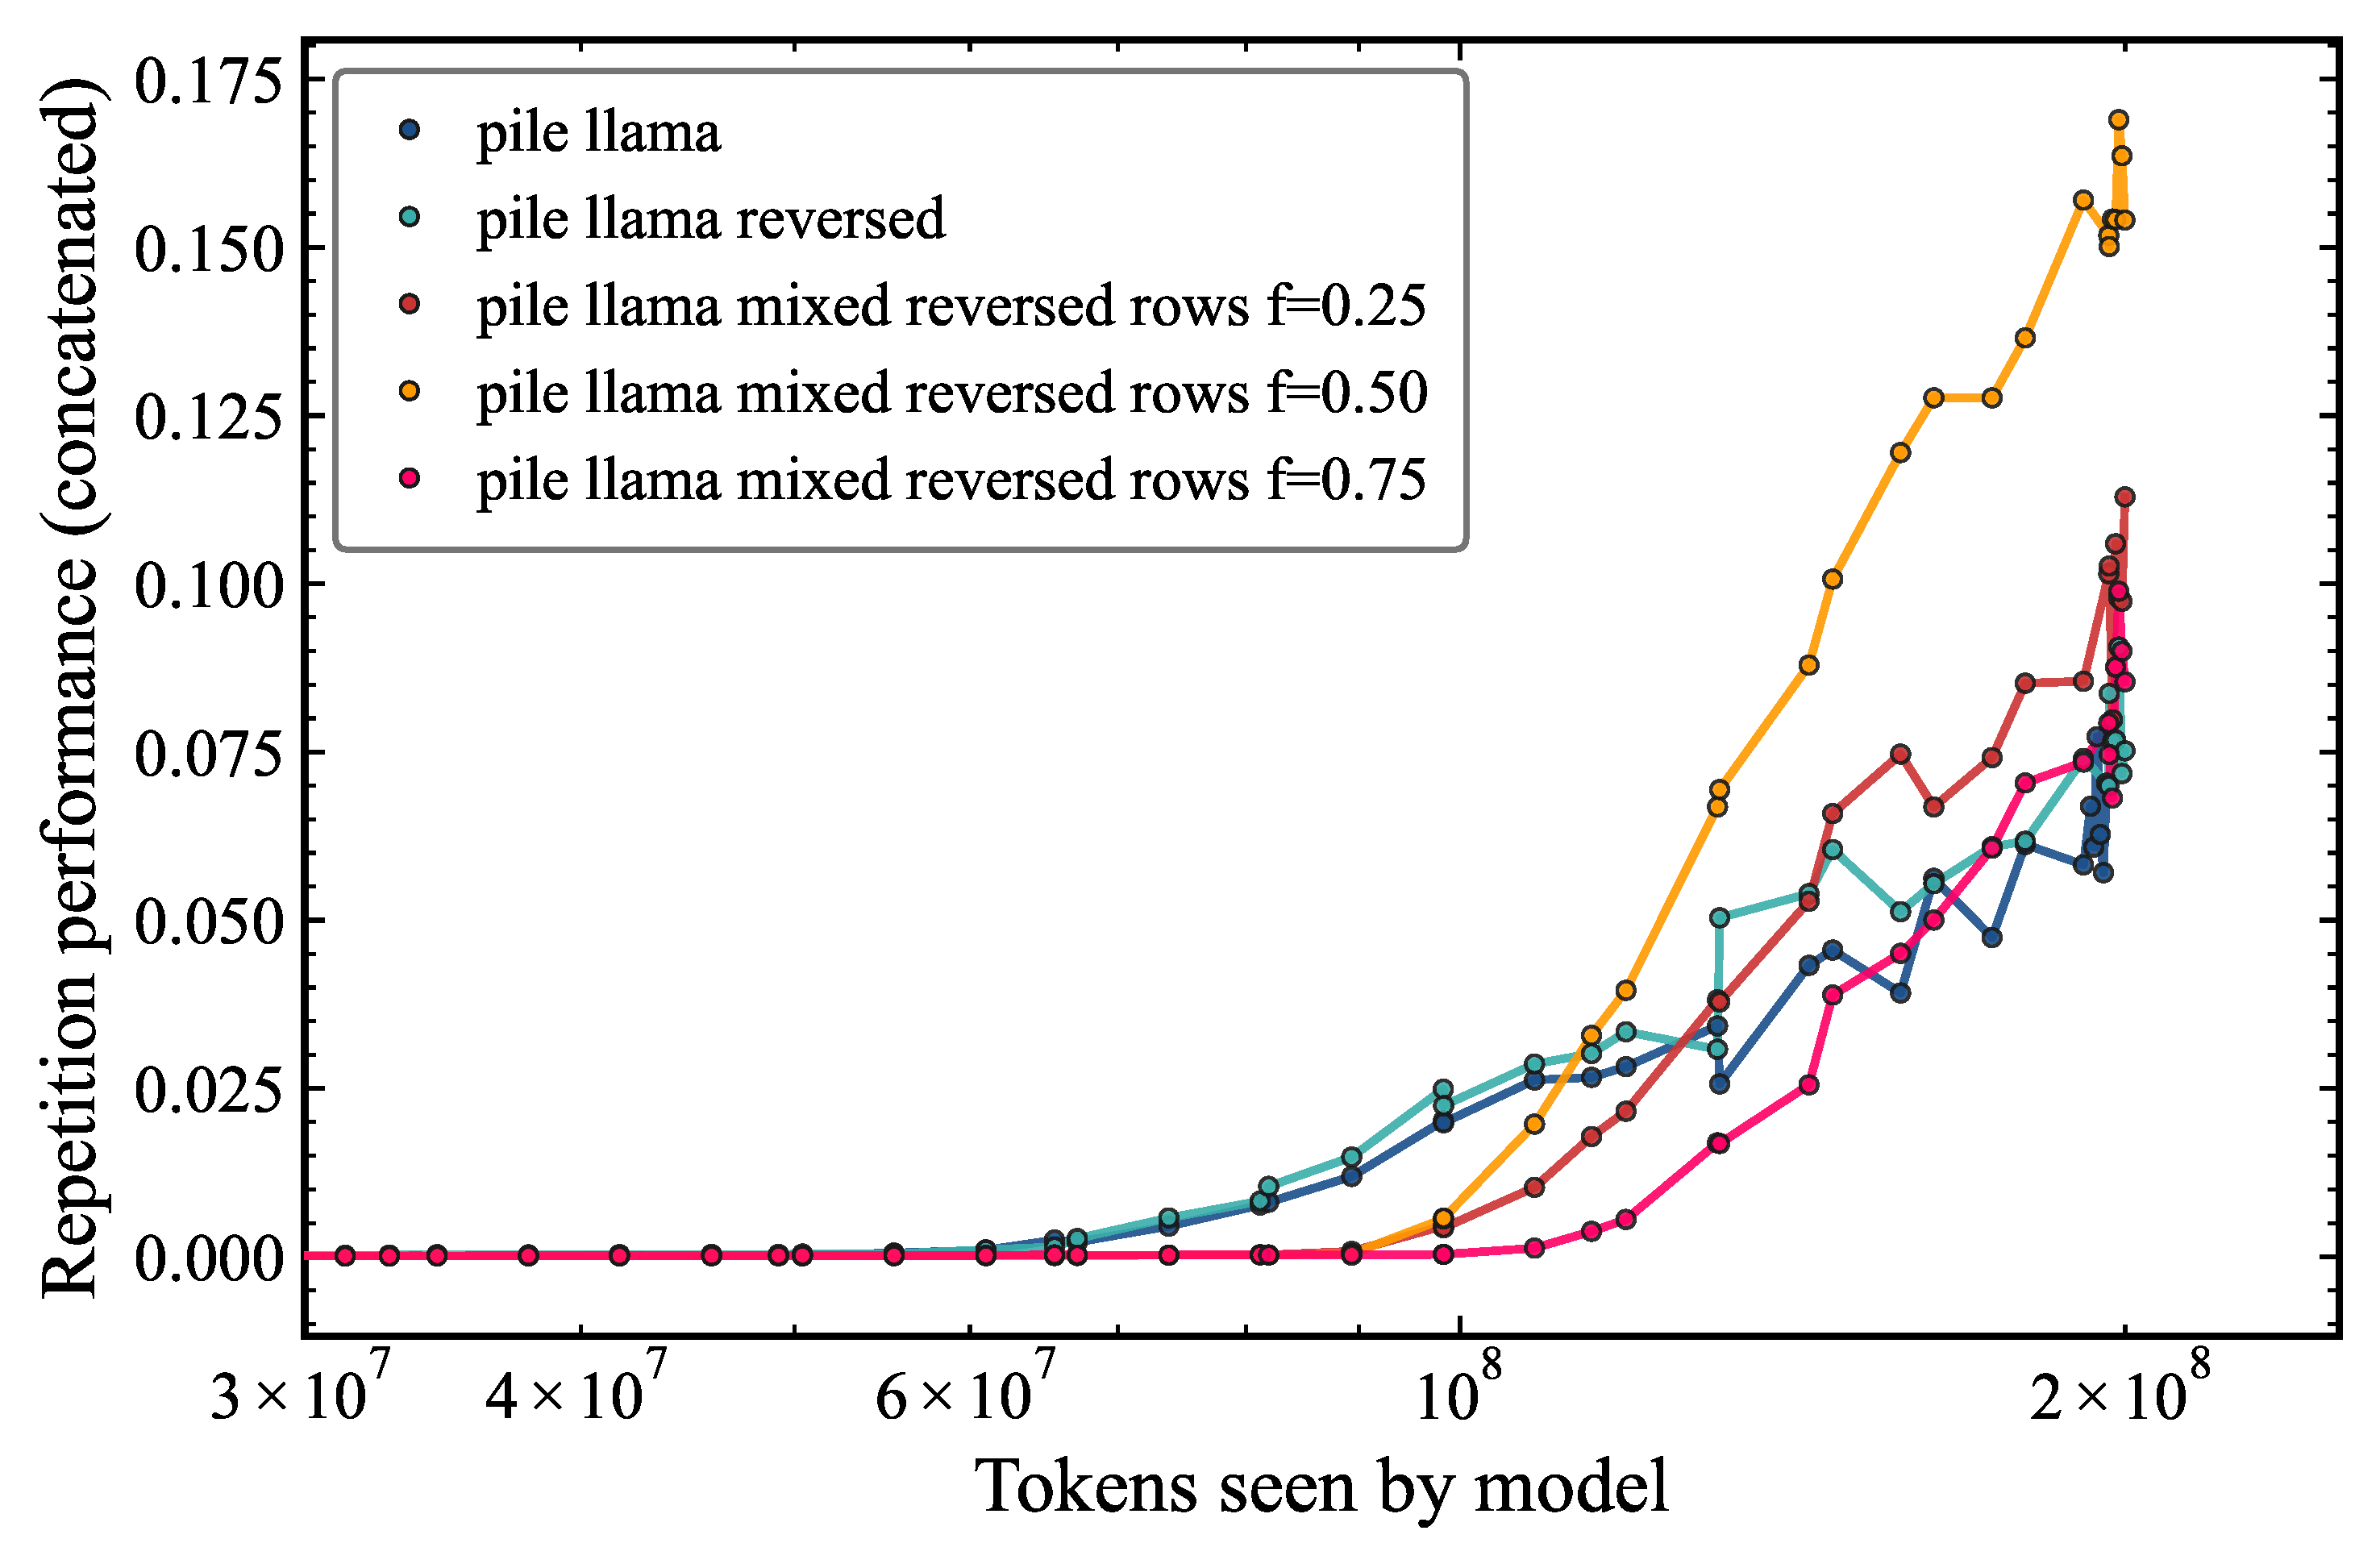
Is natural language special for learning repetition?
We reverse all tokens in the Pile dataset and find that a transformer trained on completely unnatural data still learns to repeat sequences suggesting linguistic structure is not required for induction head formation.
training-datainduction
Part 4May 2026
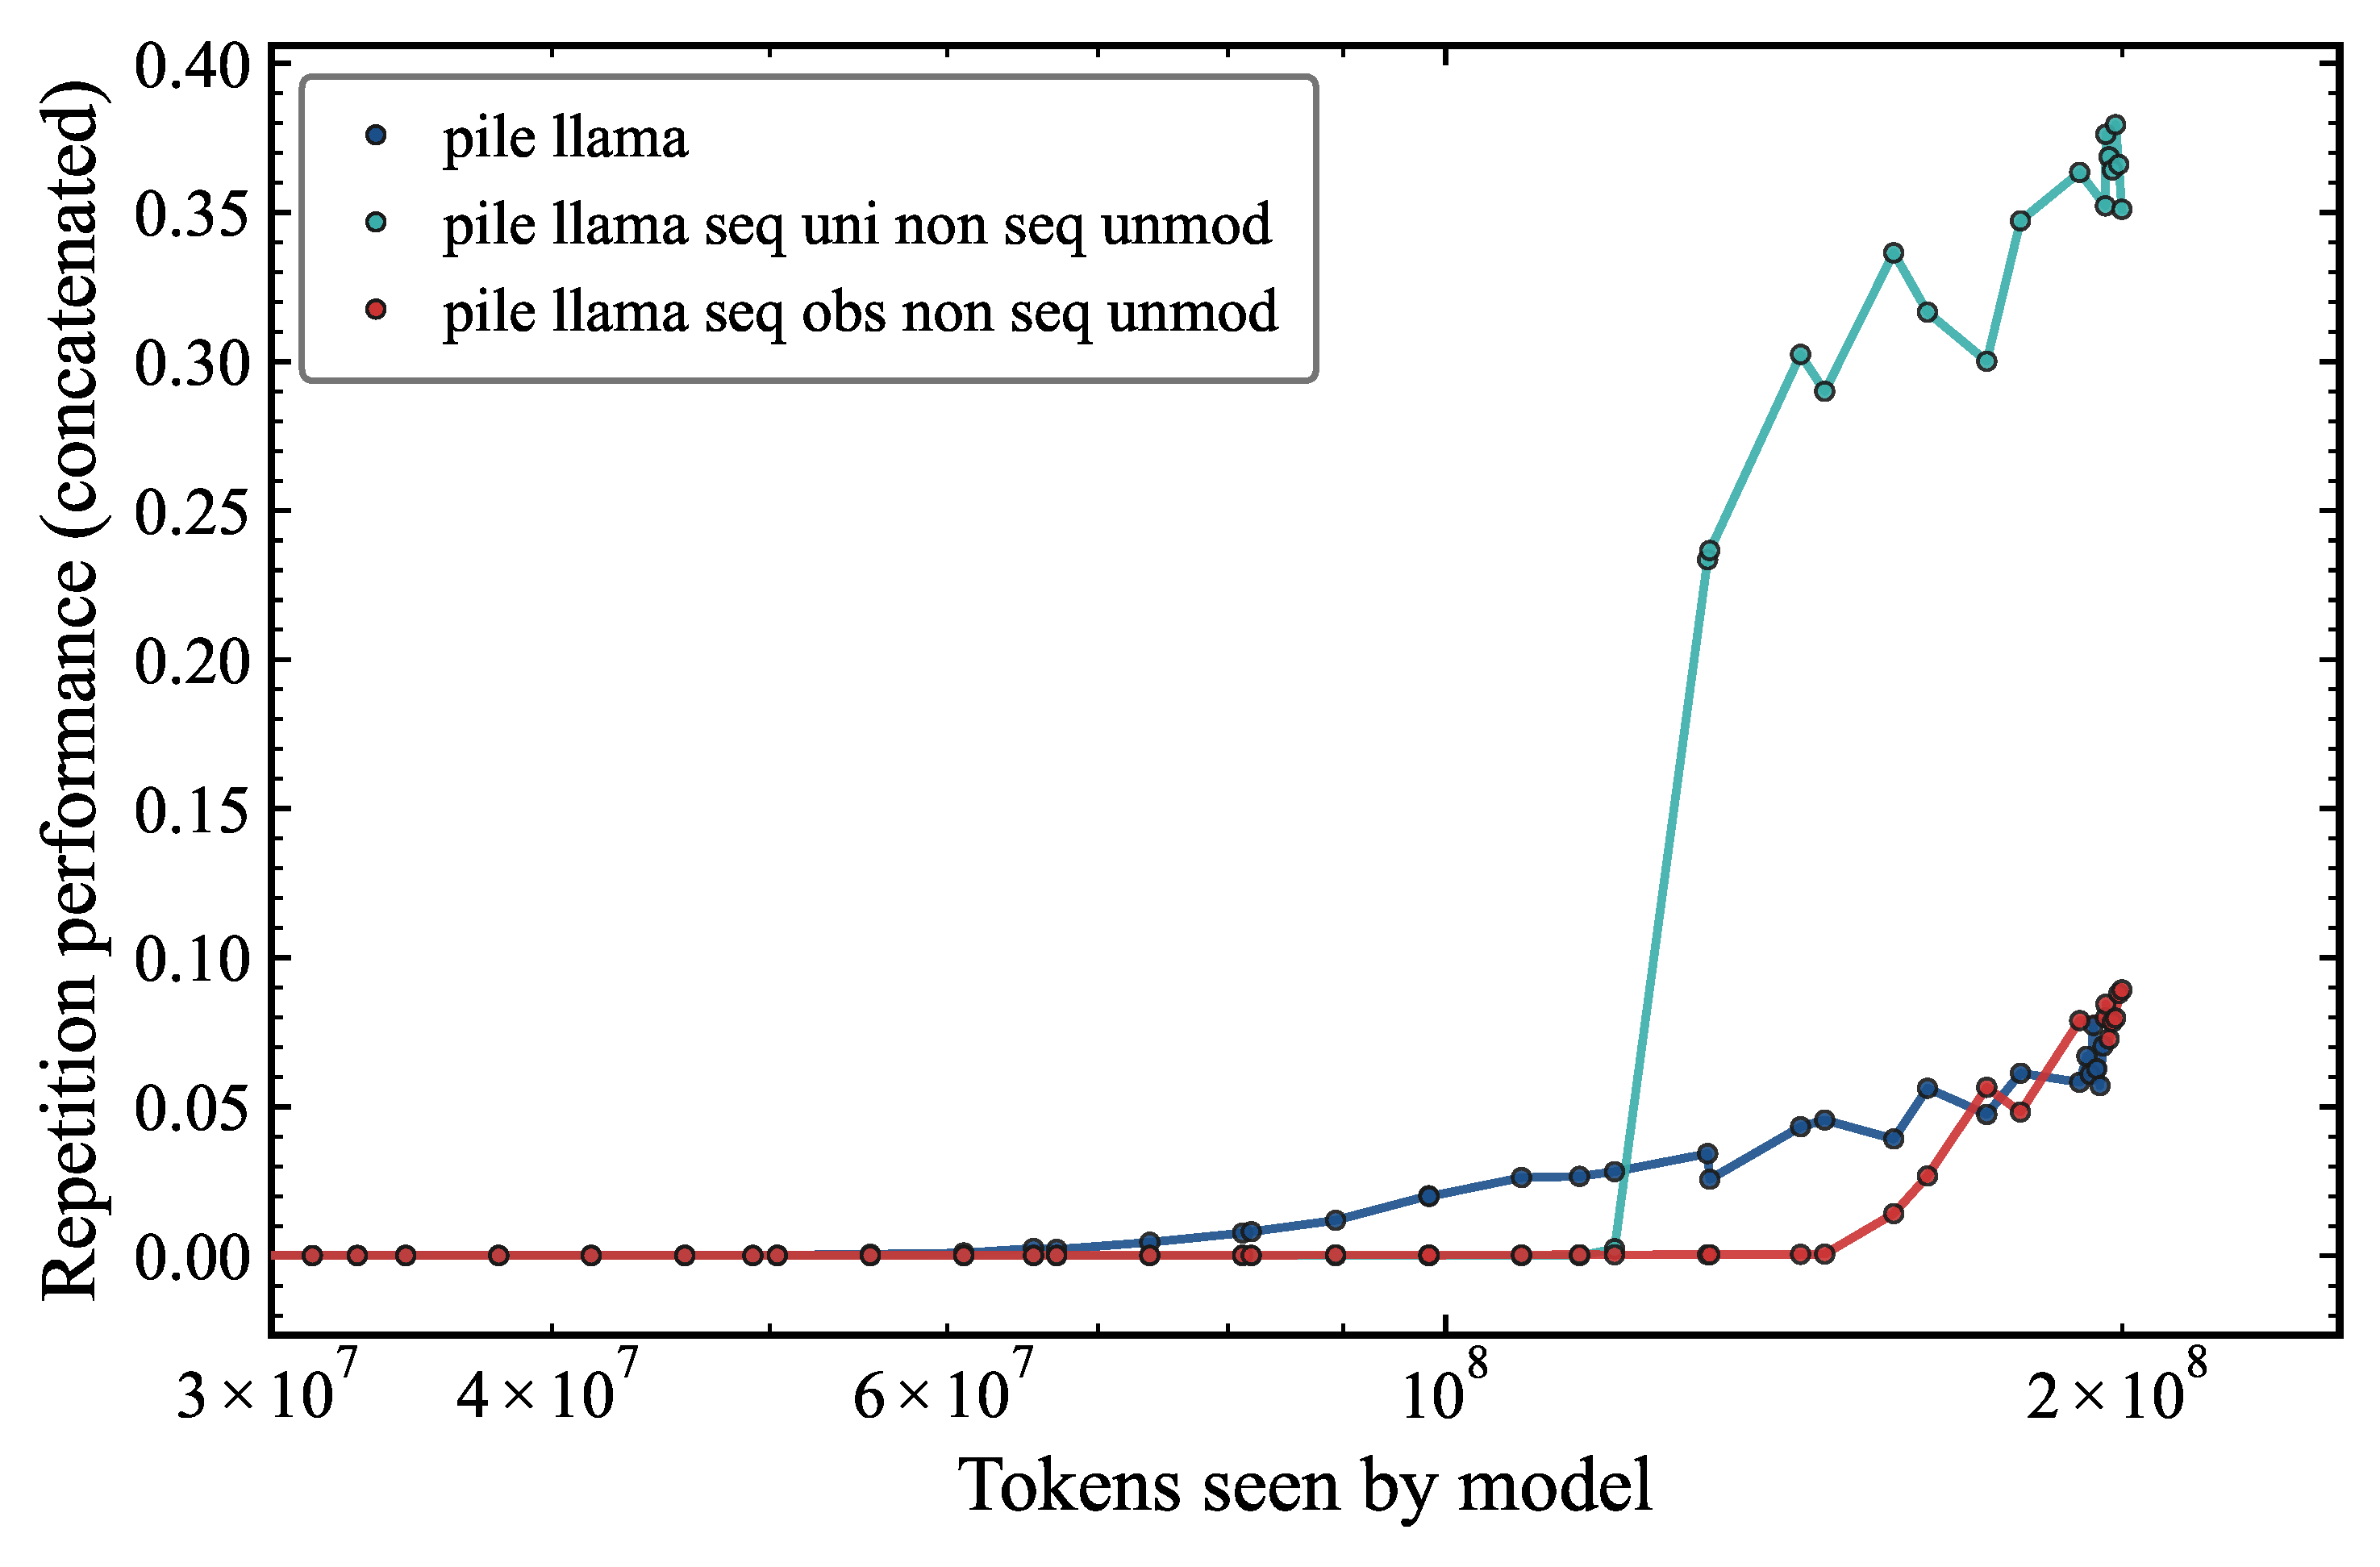
Token distribution drives repetition learning
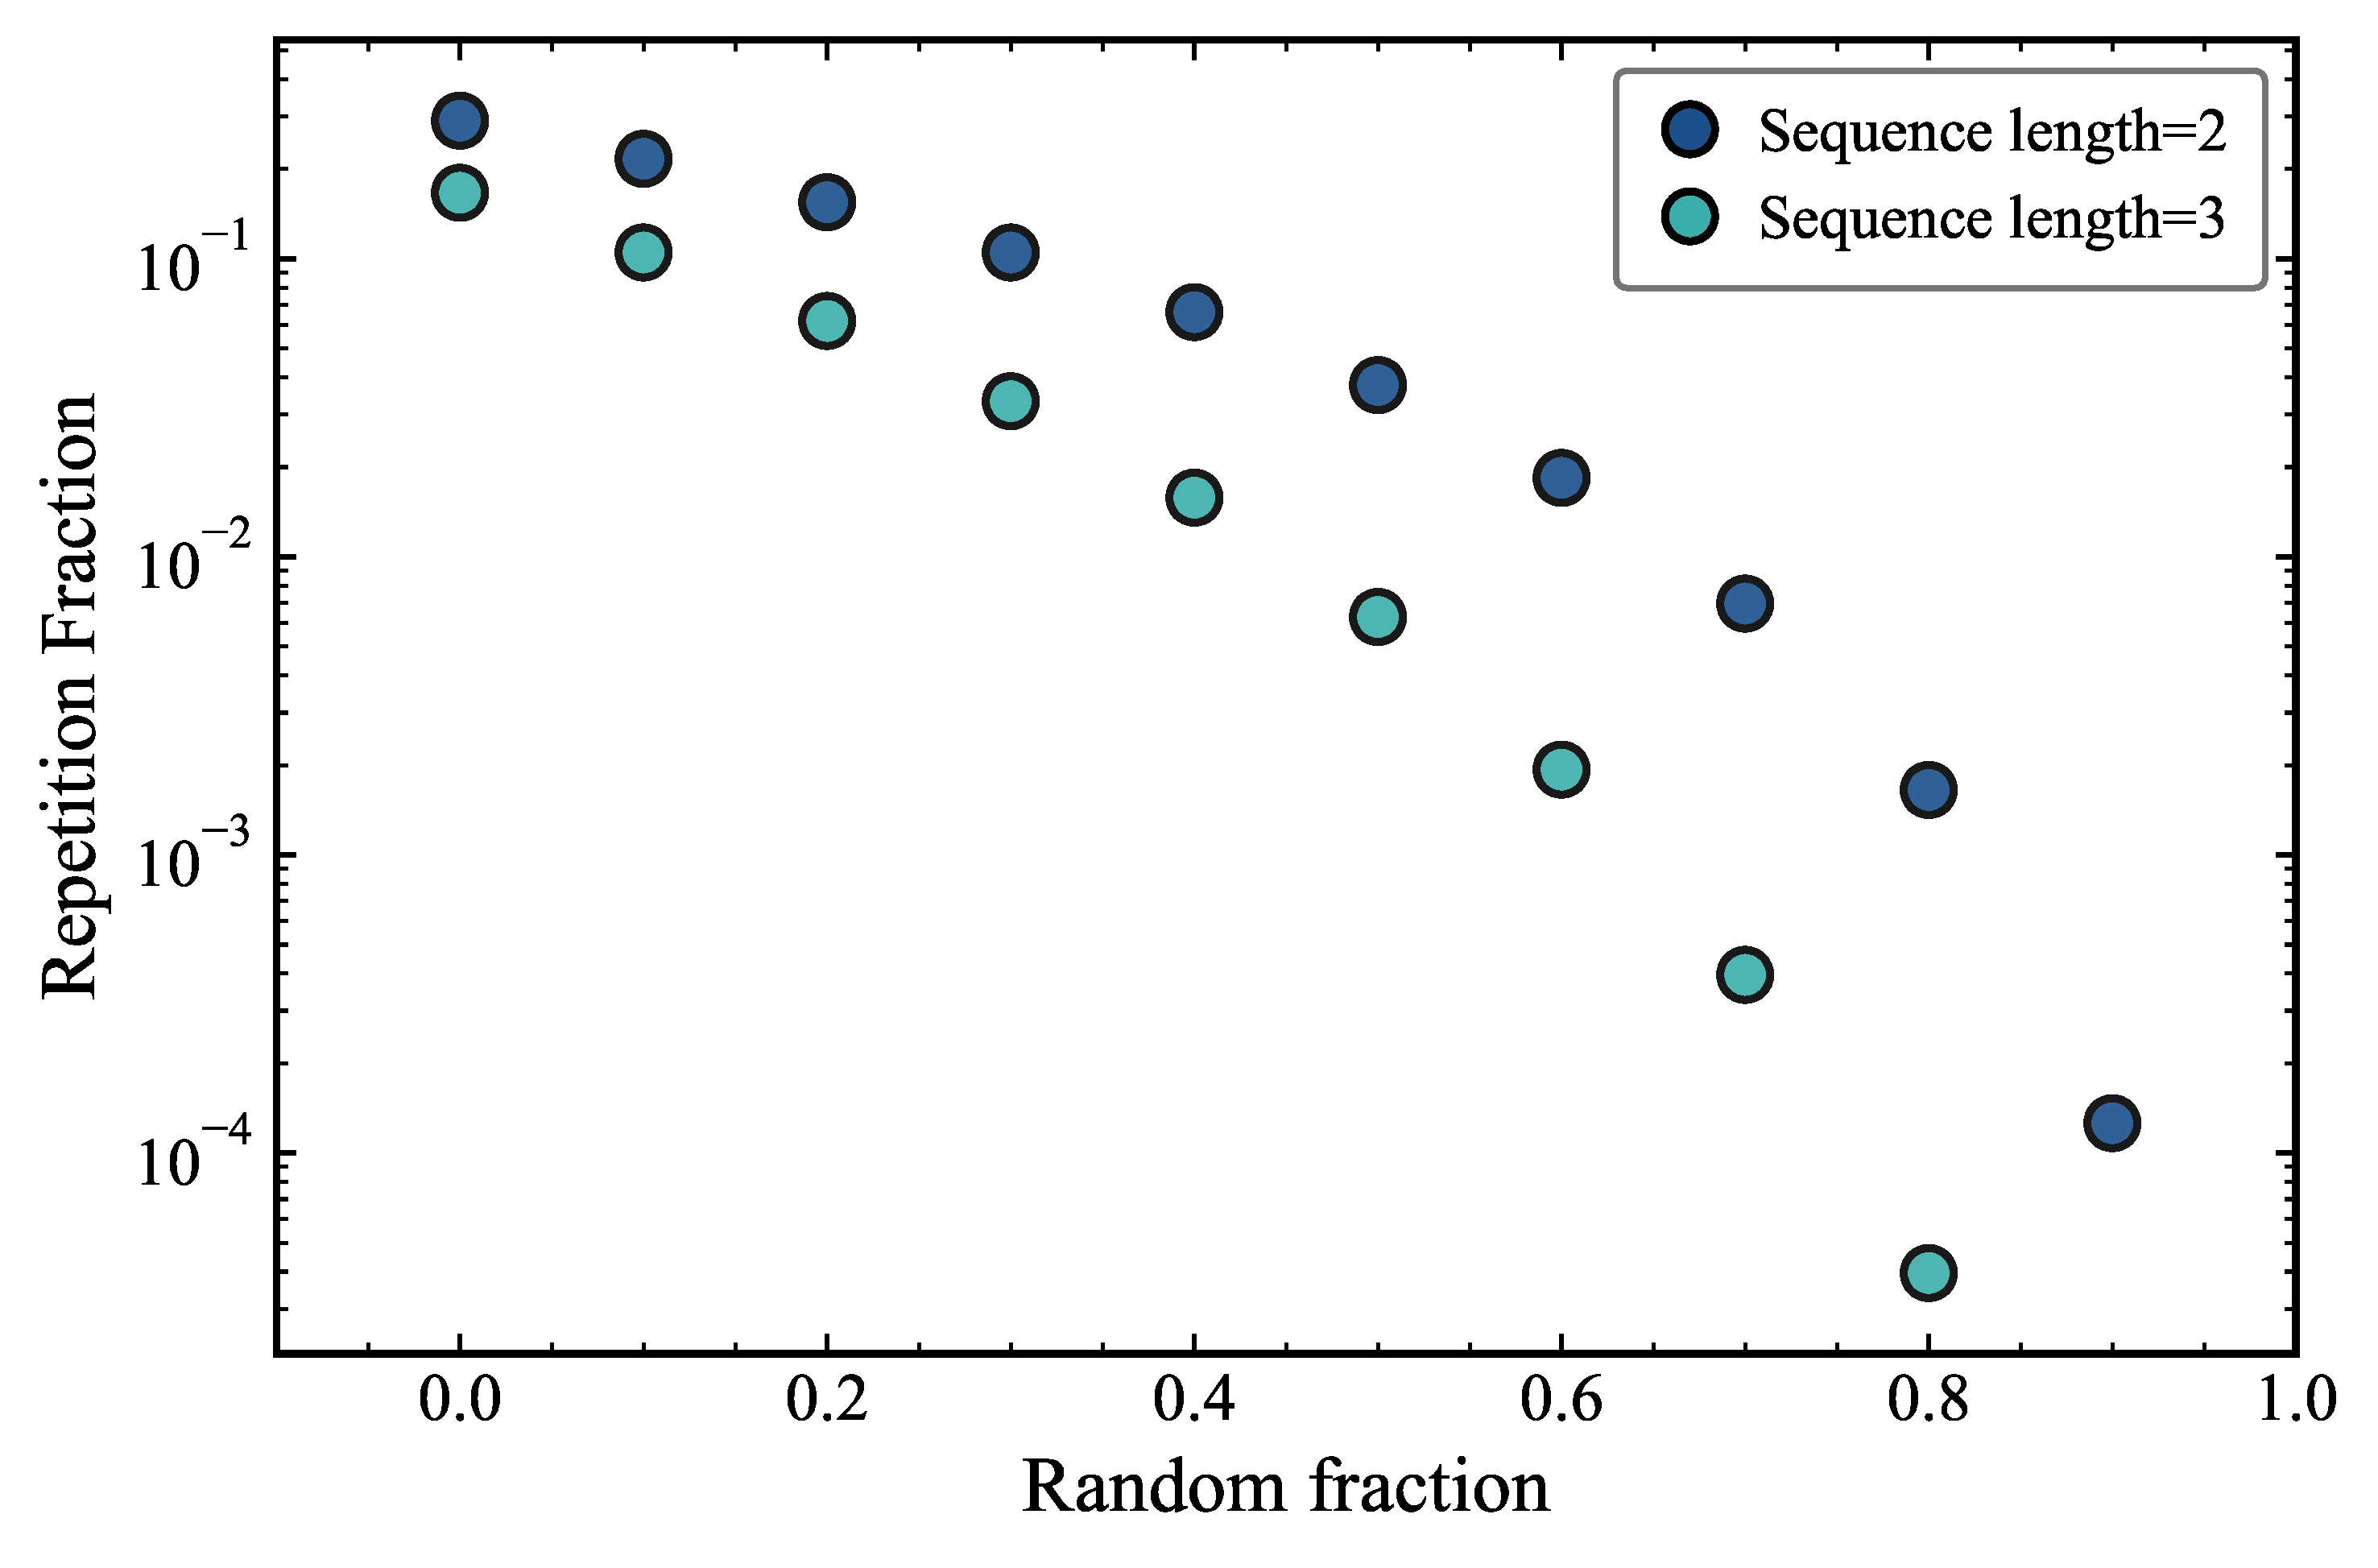
We surgically replace the tokens inside repeated sequences with random tokens, while keeping the sequence structure fixed to investigate the impact on repetition performance.
training-datainduction
Part 5May 2026
How much data does a transformer need to learn repetition?
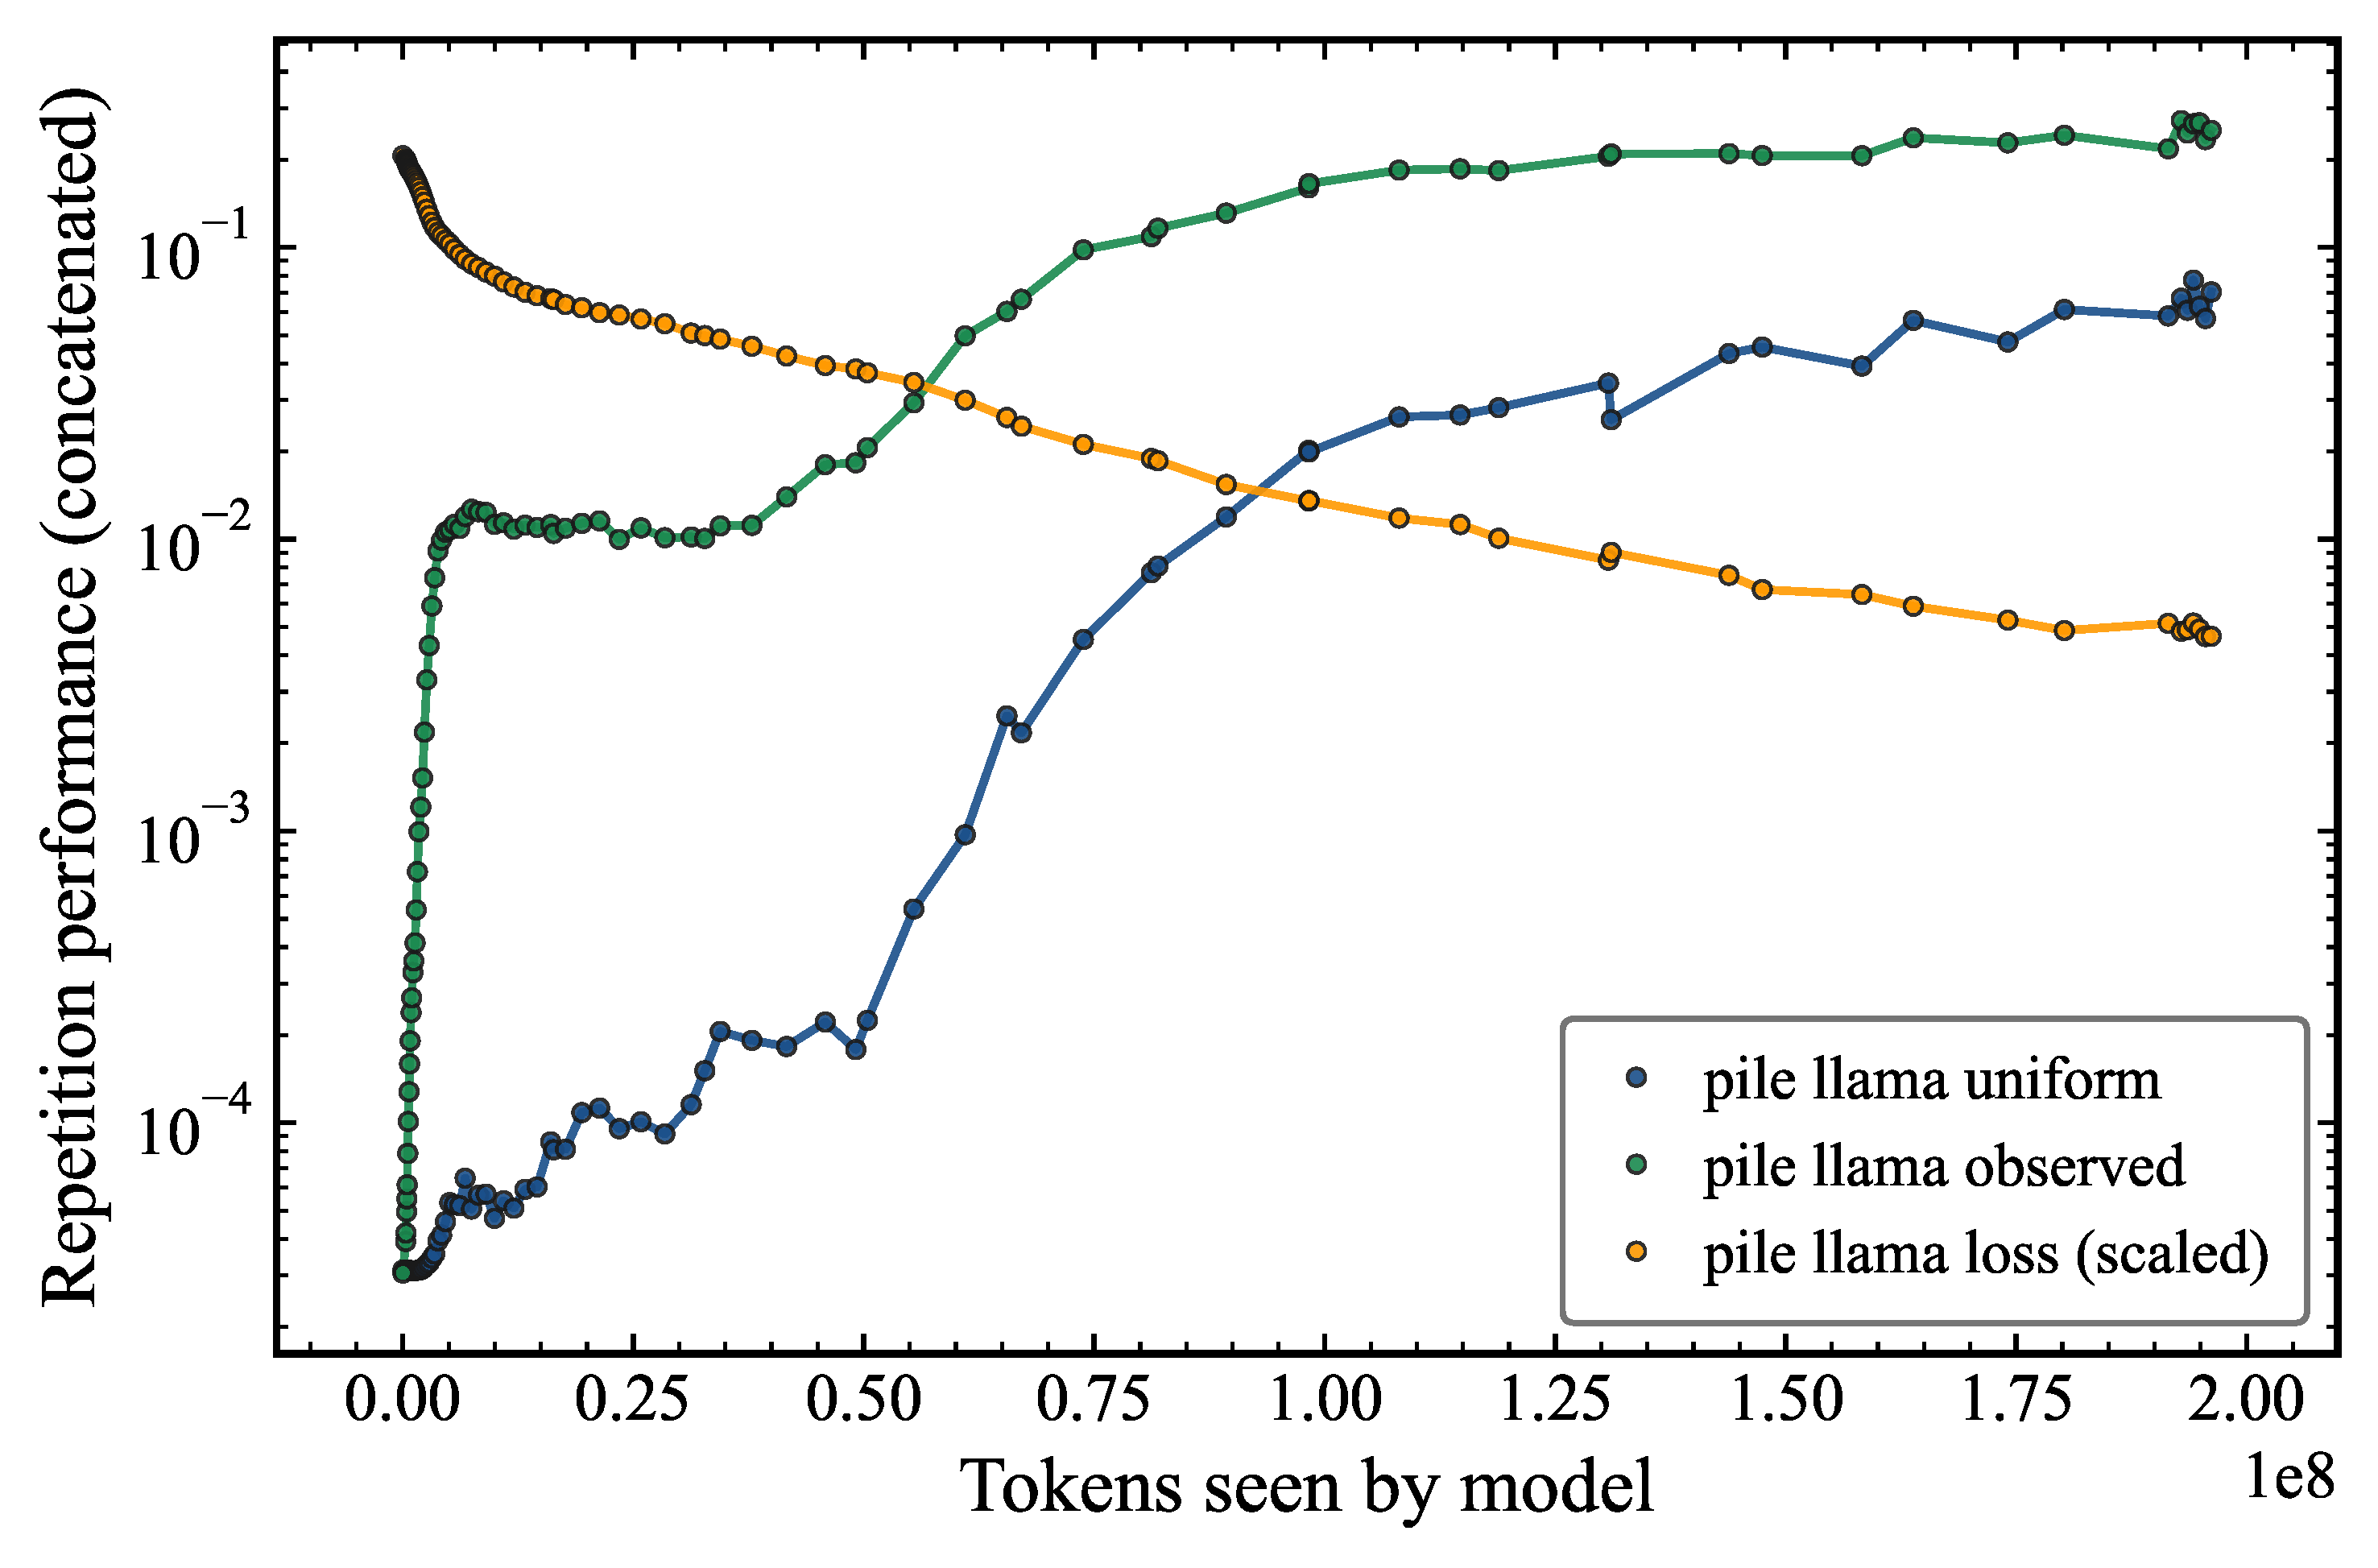
We systematically degrade the repetition signal in the training data, token by token, and row by row, and find a critical threshold below which induction heads cease to form. Even 10% of tokens in repeated sequences is enough.
training-datainduction
Part 6May 2026
Is induction a memorized or generalized capability?
We probe whether the repetition capability of our toy transformer reflects genuine generalisation or memorisation of the training distribution. A single-token experiment reveals an apparent illusion of generalised induction, a cautionary finding for evaluations of larger LLMs.
toy-modelsinduction